
AI WORKFLOW & DATA AUTOMATION
Make Smarter Decisions with AI-Powered Workflows and Data
AI workflow and data automation connects information from multiple sources to the actions a business needs to take. SmartEdge IT Solutions can design workflows for collecting data, transforming information, classifying records, generating summaries, triggering tasks and presenting decision-support information.
Overview
AI workflow and data automation connects information from multiple sources to the actions a business needs to take. SmartEdge IT Solutions can design workflows for collecting data, transforming information, classifying records, generating summaries, triggering tasks and presenting decision-support information. The system can connect databases, APIs, files and business applications while applying rules and AI models where appropriate. Clear data flow, validation, permissions and monitoring are important so that automated decisions can be reviewed and corrected when necessary.
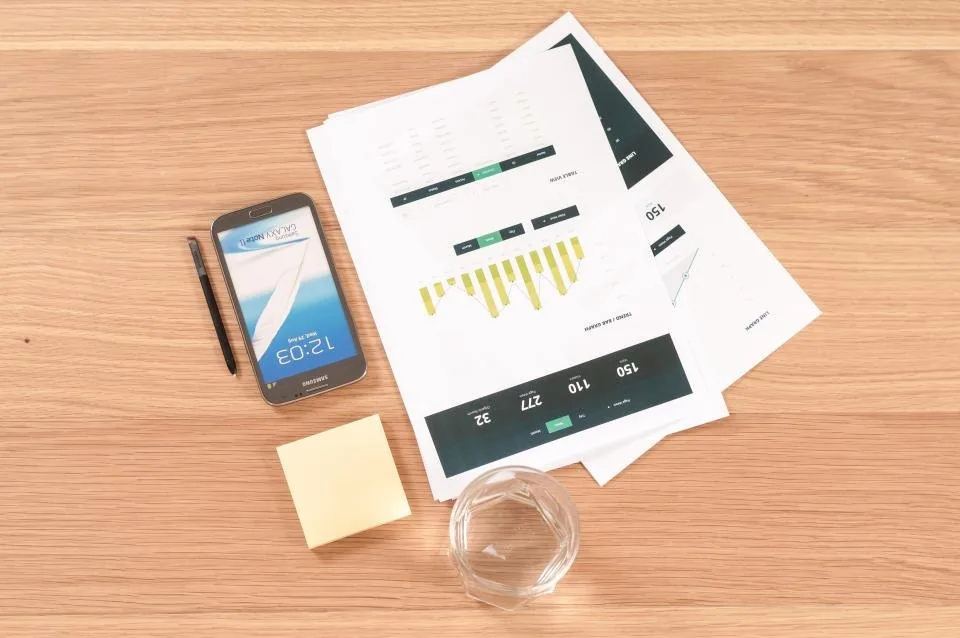
DATA FLOW ARCHITECTURE
From source to decision
Each stage below has an owner, a validation rule and a record. The stage that is usually missing is lineage: without it, when a figure looks wrong nobody can say where it came from, and the response is to stop trusting the whole system.
- Collect Scheduled or event-driven gathering from databases, APIs and files, with volume monitored.
- Validate Format, completeness and plausibility checked before anything downstream uses it.
- Transform Cleaning, joining and structuring into a usable form, with each rule documented.
- Analyse Rules where deterministic, models where interpretation is genuinely required.
- Act Tasks, notifications and record updates triggered by what the analysis found.
- Present Decision support for a person, with the underlying evidence visible.
CAPABILITIES
What the work covers
Data
- Data collection Reliable, scheduled or event-driven gathering from databases, APIs and files.
- Transformation Cleaning, joining and structuring data into a form that is usable.
- Monitoring and lineage Where data came from, what happened to it and what it triggered.
Intelligence
- Classification and analysis AI applied where interpretation is needed, rules where it is not.
- Summary and reporting Readable output rather than another data dump.
- Decision support Information assembled for a person to decide, with the evidence visible.
Action and control
- Triggered actions Tasks, notifications and record updates driven by what the data shows.
- Validation and correction Automated checks, and a route to fix what gets it wrong.
AI AND AUTOMATION
The model is one component of a working system
Python for the orchestration and evaluation code, hosted model APIs for generation and classification, Node.js where the integration is event-driven, and vector retrieval where the answer has to come from approved material rather than memory.
- Python
- SQL
- PostgreSQL
- MongoDB
- ETL and ELT pipelines
- queues
- scheduling
- AI model APIs
- REST and GraphQL APIs
- dashboards and reporting
WHY IT MATTERS
What changes when this is done properly
- Reconciliation done by the pipeline A scheduled job compares the same fields across systems on a fixed cadence, so SmartEdge IT Solutions surfaces discrepancies on a date rather than during an audit.
- Reports that arrive themselves Assembly happens from source systems rather than from an export somebody remembered to send, turning a recurring chase into a quick check.
- Sorting at volume Classification rules handle the routine share of records and pass uncertain ones to a person with evidence attached, instead of guessing quietly.
- Evidence beside the recommendation Decision support assembles what is known and shows where it came from, so a judgement can be challenged on facts rather than on trust.
- Mistakes traced to the record Lineage shows what happened to each item, which makes a correction narrow instead of requiring the whole run to be processed again.
IMPLEMENTATION PROCESS
How a data workflow project runs
- Map We map the workflow and where the data enters, changes hands and is left behind. You receive that map, since most data problems are handovers nobody has written down.
- Profile We profile the data: how much, how clean, how it changes and what can be trusted. You receive the profile, because automating over data nobody understands multiplies the original error.
- Design We design the automated flow, the validation and the exception handling. You receive the design with the points where a person must decide stated.
- Build We build it and run it against real data with the checks in place. You receive a working flow and a record of what the validation caught.
- Operate We operate it with monitoring on data quality and flow failures, and improve it as the source systems change. You receive ongoing reporting on both.
RELATED SERVICES
Elsewhere in AI & Automation
These sit alongside AI Workflow & Data Automation and cover different ground. Each has its own page if the scope turns out to be broader than this one.
TYPICAL BUSINESS CONTEXTS
Where this service is usually needed
- Data spread across systems that nobody reconciles
- Reports assembled by hand from several sources on a schedule
- Records that need classifying, routing or prioritising at volume
- Operational decisions where the relevant data is available but not assembled
- Quality control where anomalies are found by a person reading everything
COMMON QUESTIONS
Questions about this service
Not before you start. A warehouse is a significant investment and needs a data governance model behind it to be worth anything. In many cases, a well-designed pipeline that collects, transforms and delivers what a specific process needs is sufficient and far quicker to build. We will tell you when the data volume and the number of consumers have genuinely outgrown that, and we will base that on what we observe rather than on fashion. SmartEdge IT Solutions treats it as a decision point inside AI workflow and data automation, not a reason to begin on a larger platform.
Through validation at each boundary, clear ownership of each field, and visible lineage so a figure can be traced back to where it came from. Where data arrives from outside your control, we validate and quarantine rather than silently accepting it. Automated decisions always keep a route for correction, because data quality degrades over time through small changes rather than one large failure.
Wherever the decision has consequences or requires judgement. That typically means anything affecting a customer, a payment, a contract, or a person’s employment. The system’s job is to assemble the relevant information and present it clearly; the decision stays with someone accountable for it. Where a decision is genuinely mechanical and the evidence is complete, automating it is reasonable — with an audit trail either way.
Then the workflow needs to be correctable rather than trusted blindly. Every automated decision is logged with its inputs, so you can see why it was made; outputs can be corrected and the correction fed back; and thresholds can be adjusted without a redeploy. We design for the assumption that some outputs will be wrong, because in a system that runs unattended, some will be.
The run is recorded as failed rather than half-finished, and someone finds out before a colleague notices a stale figure. Each stage stores its status and inputs, failures retry a bounded number of times, and a run that cannot complete leaves the last good data in place with a visible flag rather than publishing an empty result. Alerts go to a channel people actually read, with enough detail to begin. We set observability up as described in our DevOps consulting.
Retention is set per dataset rather than by one global rule, because the obligation differs by data type and by sector, and only your compliance owner can state it authoritatively. SmartEdge IT Solutions implements it as scheduled, logged deletion preceded by a dry run, so you can see what would go before anything is removed. Raw personal data is kept separate from derived records so removing the source is sufficient, and every deletion event is recorded for whoever asks about it months later.
Not at first. Spreadsheets usually hold real knowledge alongside the manual work, so we look at what each one produces and who depends on it before replacing anything. A sequence that works is to automate the collection and calculation while leaving the familiar view in place, then move people across once they trust the figures. Removing a spreadsheet that still has an owner and no working replacement is a common way automation projects lose internal support. We work through this during our discovery process.
It depends on whether the process can wait. Anything that must happen by a fixed time, such as month-end figures, nightly syncs or reminders, is scheduled and can be retried safely. Anything driven by an event, a new record or an uploaded file, runs on a queue so a burst does not overwhelm the downstream system and quiet periods do not leave workers idle. Most real pipelines use both, and SmartEdge IT Solutions keeps the trigger logic explicit so behaviour is predictable at three in the morning as well as at midday.
LET'S BUILD TOGETHER
Ready to Build Something That Actually Works?
Tell us what you are trying to achieve. We will help you work out the right approach, the right technology and a realistic plan to get there.